On this page
When a recruiter uploads a CV to EvalCV, a number comes back a few seconds later. This post walks through what happens in between, and what the model is and is not shown.
Step 1: Turning a PDF into text
CVs arrive as PDFs, Word files and the occasional image. We extract text with layout awareness, because two-column designs read in the wrong order if you take the text stream as it comes. If extraction produces too little text, the CV is flagged for human review instead of being scored on nothing.
Step 2: Removing signals that should not matter
Before anything reaches the model, a redaction step removes fields that are irrelevant to the job and correlate with protected characteristics.
- Name and photo
- Date of birth and graduation years
- Home address
- Marital status and nationality where stated
The list of removed fields is stored with the result so it can be audited later.
Step 3: Reading the job description
The job description is parsed into discrete requirements, each marked as required or preferred. Recruiters can edit this list before any scoring happens, which matters: the score is only as good as the requirements it is measured against.
Why requirements, not outcomes
We do not train on who was hired before. A model that learns from past decisions inherits their patterns. Scoring against written requirements is less clever and far easier to explain.
Step 4: Matching with evidence
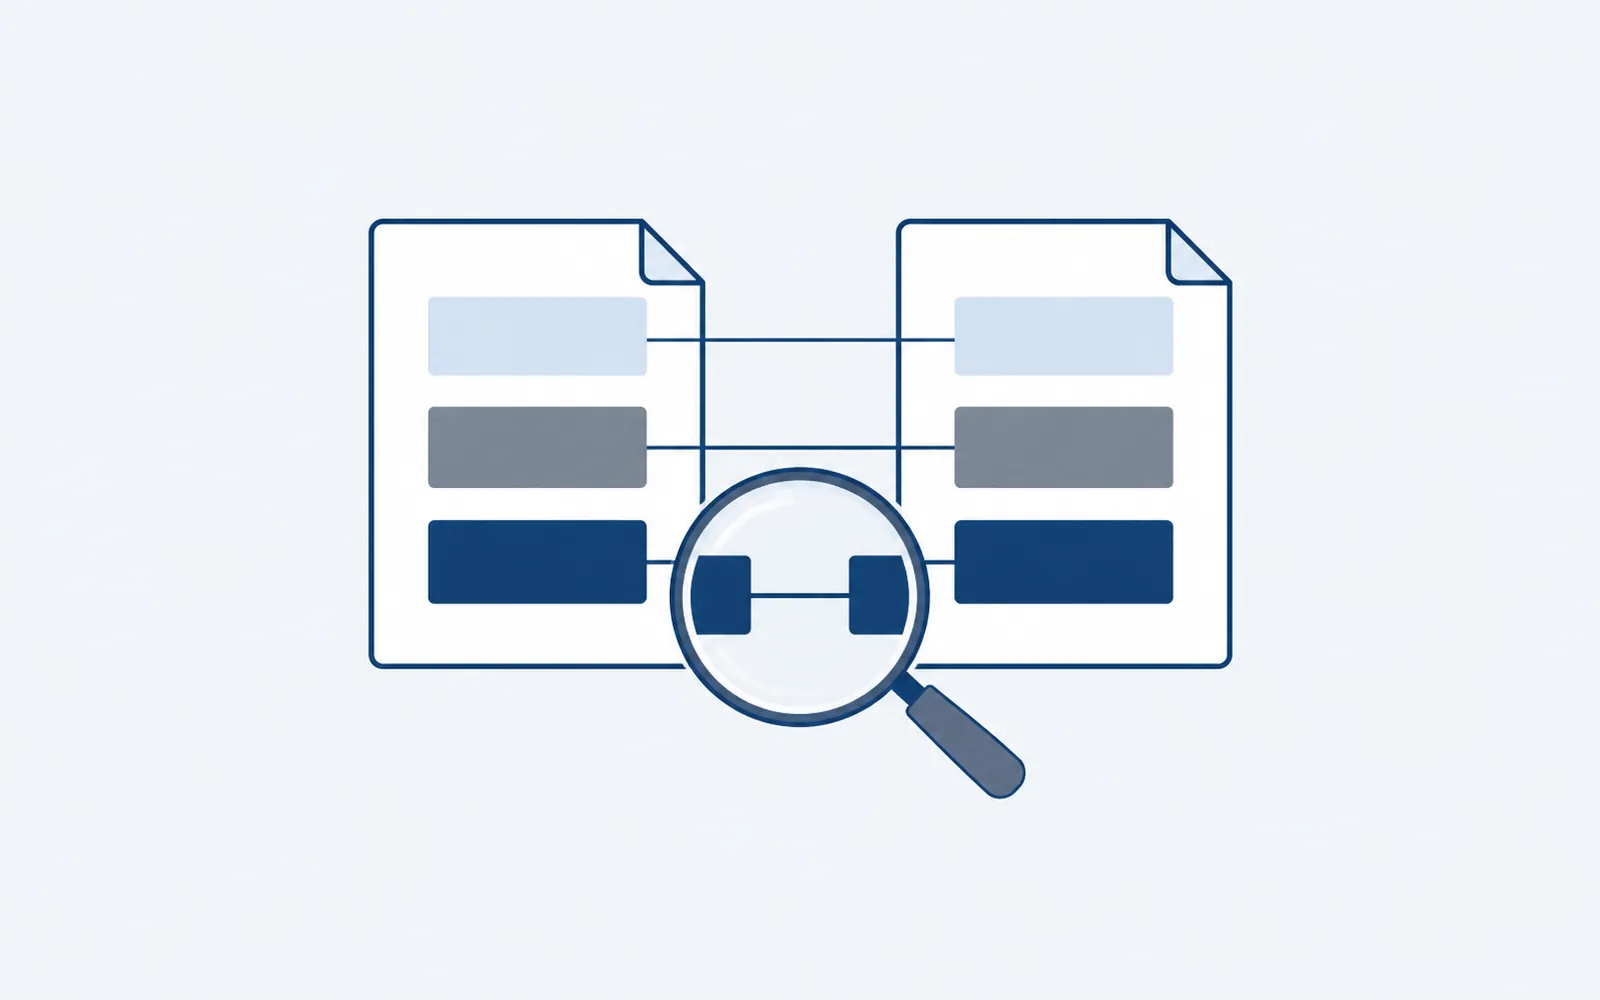
For each requirement, the model must either quote a line from the CV that supports it or mark it as missing. A match without a quote is discarded.
{
  "requirement": "PostgreSQL",
  "status": "matched",
  "quote": "Tuned slow queries on a 2 TB PostgreSQL cluster"
}
This is the step that makes a score checkable. A recruiter can read the quote and decide whether it really satisfies the requirement.
Step 5: Combining into a score
Matched required items carry more weight than preferred ones, and missing required items are shown prominently rather than averaged away. The final number is a summary. The matched and missing lists are the real output.
Where it goes wrong
- Implied experience. A CV that says "led a team of five" does not say "managed people", and the model can miss the link.
- Unusual formats. Heavily designed CVs lose structure in extraction.
- Vague job descriptions. Vague requirements produce vague matches.
The human stays in charge
EvalCV produces a shortlist and the reasons for it. It does not reject anyone on its own. Every result can be overridden, and overrides are logged, which also tells us where the pipeline is wrong.
Found this useful? Share it with your hiring team.
Share on LinkedInRelated product
EvalCV
AI Hiring
AI CV screening API and recruiter portal that scores candidates against a job description in seconds.